Agentic Inference for MLPerf Inference
MLCommons ·
A new multi-turn benchmark for measuring LLM serving systems under growing context, and closed-loop agent workflows. The post Agentic Inference for MLPerf Inference appeared first on MLCommons .
The MLPerf Inference benchmark suite must evolve alongside AI deployment patterns. Early inference benchmarks focused on image classification, object detection, speech recognition, recommendation, and single-turn language generation. Those workloads remain important, but they no longer cover one of the fastest-growing ways large language models are used in production: multi-turn agentic inference .
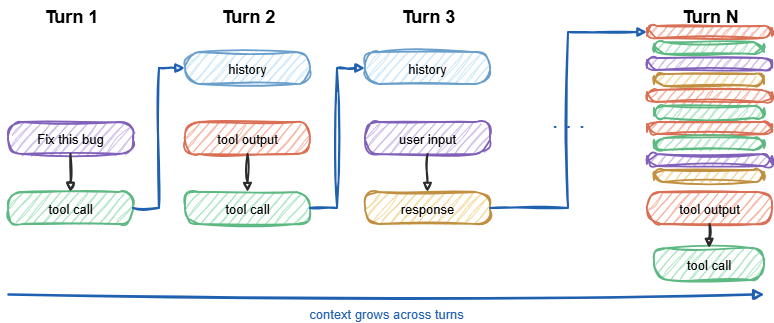
For example, a coding assistant is far more complex than a single query. The agent will read an issue, inspect files, run commands, observe failures, edit code, and iterate potentially many times. Similarly, a workflow agent gathers customer information, calls tools, interprets results, asks follow-up questions, and continues until the task is resolved. In both cases, the workload is a trajectory : a sequence of dependent turns where each request includes the conversation history up to that point.
This changes the serving problem in four concrete ways:
Figure 1. Illustration of an agentic inference scenario involving multiple turns.
The Agentic Inference benchmark adds this class of workload to the MLPerf Endpoints framework . It keeps the general MLPerf measurement principles intact while defining the workload-specific pieces: model choice, dataset composition, multi-turn load generation, output validation, and constraints for optimizations such as prefix caching and speculative decoding .
The benchmark needs long-context, thinking-capable LLMs that stress the serving behavior of agentic applications: growing context, KV-cache reuse, variable output lengths, and strict turn dependencies. For this benchmark, we chose Kimi K2.6 and Qwen3.6-35B-A3B . Kimi K2.6 brings state-of-the-art coding capability and a large model profile representative of leading agentic systems; Qwen3.6-35B-A3B is more compact and brings a new Gated DeltaNet (GDN) architecture and exceptional coding performance for its size. This gives the benchmark coverage across distinct serving behaviors, architectural choices, and speculative-decoding paths. Both models are evaluated with the same methodology and dataset. To avoid ambiguity, each model produces its own result; the two models are not run together or combined into a single score.
Table 1. Model metadata and benchmark settings
The benchmark dataset combines two agentic domains that exercise different infrastructure bottlenecks. Together, they contain 613 multi-turn trajectories : 113 agentic coding trajectories and 500 agentic workflow trajectories . Across the reference dataset, these trajectories contain 30,335 client-issued turns and 30,328 assistant turns. By using real collected traces for benchmarking, the workload simulates real-world behavior in the serving stack, including how speculative decoding and expert-rank balancing behave under realistic multi-turn traffic.
Table 2. Dataset composition and mean token statistics
The agentic coding traces come from the DeepSWE dataset by DataCurve (datacurve.ai) , which contains software engineering tasks built around repository-level bugs and feature requests. A typical trace begins with a user request describing an issue, followed by an assistant that investigates the repository through a series of bash commands . The agent searches files, reads code, runs tests, observes errors, edits the implementation, and iterates. These traces are deep: the median trajectory contains dozens of turns, and the conversation history grows steadily as command outputs, file contents, and test logs accumulate.
The Workato agentic workflow traces come from enterprise customer-support and orchestration scenarios. They represent interactions where a simulated customer asks for help and the agent uses tools to retrieve orders, track shipments, check policies, escalate cases, or resolve account questions. These trajectories are usually shallower than the coding traces, but they include a much larger shared system prompt with many tool definitions and business rules. The agentic workflow traces were provided by Workato, the agentic control and execution plane for the enterprise. The data are synthetic traces modeled on Workato’s production experience orchestrating customer support agents for enterprise customers.
The two domains are intentionally different:
We introduced multi-turn support to MLPerf Endpoints so the benchmark can drive full end-to-end agentic workloads against standard serving stacks. Submitters simply need to spin up an OpenAI-compatible endpoint using vLLM, SGLang, TensorRT-LLM, or another serving framework, then point the client at that endpoint for full end-to-end benchmarking.
The client handles the multi-turn behavior:
The primary performance chart is a Pareto curve where each point is a fixed-concurrency benchmark result . Submitters need to submit a full Pareto curve as defined in the MLPerf Endpoints rules.
The two axes represent complementary views of the serving system. The x-axis, output tokens per second per user, captures how quickly an individual agent progresses through its task; moving right means faster task completion. The y-axis, output tokens per second per system, captures the total work completed across all active agents; moving up means greater aggregate throughput and higher system utilization. As concurrency increases, the system may complete more total work while each individual agent progresses more slowly. The Pareto curve makes this tradeoff visible.
Figure 2. Chart illustrating agentic inference performance
Accuracy is enforced as a three-level hierarchy so the Pareto curve measures usable agentic progress rather than responses that are shorter, lower quality, or easier to serve.
All three levels must be run for every point on the Pareto curve, and each score must meet a pre-defined threshold. Thresholds are defined separately for each level and for both Kimi K2.6 and Qwen3.6-35B-A3B.
Table 3. Tentative accuracy values, subject to change.
Submitters only need to spin up an OpenAI-compatible server using vLLM, SGLang, TensorRT-LLM, or another serving framework, then point the MLPerf Endpoints client at that endpoint to run the full benchmark. The MLPerf Endpoints Agentic Inference README includes the example configs, command lines, and setup steps.
Agentic inference is one of the fastest growing applications of AI today and it’s far more complicated than existing single-turn text generation. Agentic workflows have serving patterns with unique constraints: growing context, strict turn dependencies, tool-mediated delays, shared prefixes, long-tail trajectories, and output quality checks that must run on the same configuration used for performance.
The Agentic Inference benchmark brings those constraints into MLPerf in a reproducible form. By combining deep coding trajectories with shared-prefix workflow trajectories , it measures whether serving systems can make progress for real multi-turn users while still using hardware efficiently.
As agentic applications become a larger share of production LLM traffic, the industry needs benchmarks that measure the systems work that actually matters: preserving cache locality, scheduling long contexts, maintaining output quality, and balancing aggregate throughput with per-user progress . This benchmark is a step toward that measurement standard. If your team is building serving infrastructure for multi-turn agents, join MLCommons to access the reference implementation and submit results
The post Agentic Inference for MLPerf Inference appeared first on MLCommons .