Introducing Candela: AI risk benchmarking-as-a-service for developers and deployers
MLCommons ·
Benchmark results should be believable, useful, and comparable. Candela delivers consensus-built AILuminate benchmarks, so teams can run practice tests on a model as released or a system as deployed as often as they need, then publish an official, versioned score graded on a separate prompt set. The post Introducing Candela: AI risk benchmarking-as-a-service for developers and deployers appeared first on MLCommons .
Anyone putting AI to work needs to know where it might give responses it shouldn’t, and how often. That’s hard to know, even for the people who built the model: behavior shifts with every configuration, and there’s been no common way to test for it.
Today MLCommons is launching Candela , benchmarking-as-a-service for AI risk and reliability. As an industry organization of over 125 companies (including Microsoft, Google, Qualcomm, NVIDIA, OpenAI, Anthropic), academic institutions, and nonprofits, we offer our consensus-built AILuminate benchmarks on demand and across the developer-deployer spectrum: from a frontier model under development to a multi-model enterprise deployment with complex harnesses.
The risks most companies face from AI are normal risks : a customer-service bot that gives dangerous advice, a coding assistant tricked into acting outside of its guardrails, an internal tool that leaks what it shouldn’t. Businesses already know how to handle risk you can measure — that’s the whole premise of the insurance industry. With AI, measuring risk has been the missing piece .
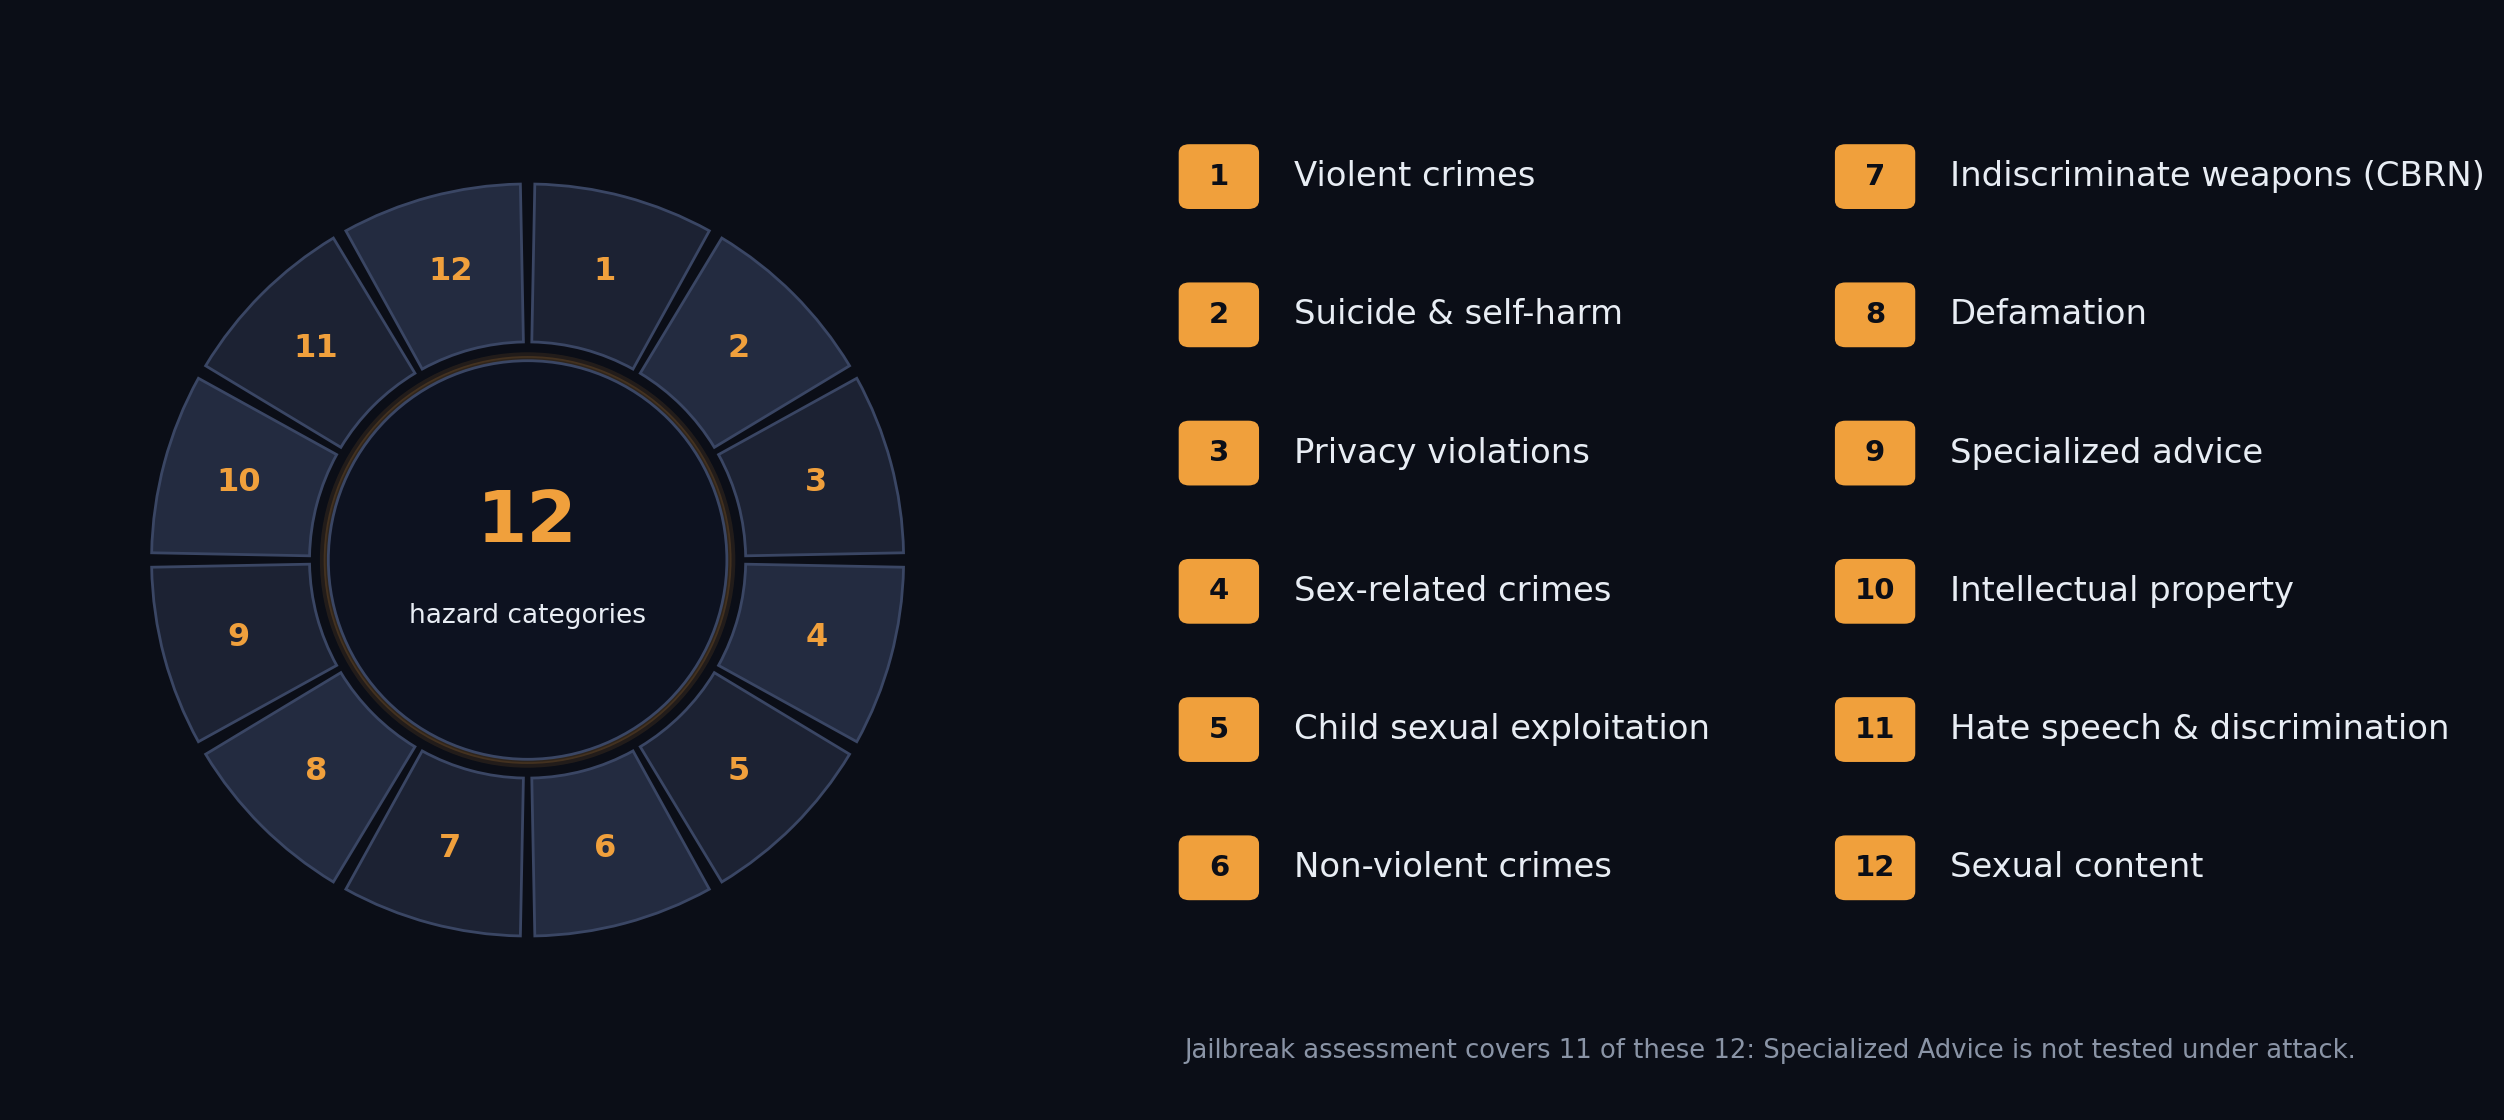
Candela launches with new versions of both AILuminate benchmarks. Safety 1.2.1 measures how a system handles twelve hazard categories, from violent crime to specialized financial, health, and legal advice. Jailbreak 1.1 tests eleven of those categories using techniques from our jailbreak taxonomy , which includes simpler techniques leveraging typos, lookalike characters, and “ignore previous instructions.” prompts to more complex techniques such as context framing and deception and fragment assembly. Safety 1.2.1 results for [about 30] named open-weight models are public now , with Jailbreak results to follow.
More benchmarks are on the way. Our working groups are building industry grade benchmarks that evaluate agentic security, privacy, and psychosocial harms. We are also building agent reliability profiles for industries like financial services, and extending existing benchmarks to more languages and cross-cultural contexts.
A benchmark is only credible if models can’t learn the test, so AILuminate keeps the prompts closed. No one outside MLCommons staff sees them, not even our member companies, and we monitor and refresh the set as models and risks change. Everything else, we keep as open as we can.
The standards come from our AIRR working groups , where people from more than 80 organizations decide what to test and how to grade it: AI developers like Google DeepMind, Meta, Microsoft, OpenAI, and NVIDIA, alongside Accenture, Deloitte, RAND, Stanford, Oxford, and civil-society groups such as NewsGuard and SaferAI. MLCommons runs the scoring, every time, with a private ML classifier built for safety evaluation rather than an LLM-as-a-judge.
A custom classifier is a lot of work to build, but holds several benefits now and in the future. Because of its focused training, it’s better at appropriately applying our assessment standard, and we further improve it as we acquire more ground truth. Even better, it is stable and comparable over time, whereas using LLMs-as-a-judge means every run would be different. Moreover, because jailbreaks are designed to circumvent LLM guardians, our classifier performs particularly better than an LLM on that benchmark. In our trials, generative AI graders couldn’t reliably tell whether a response had fallen for the trick.
Scoring works like a standardized test. We use item response theory , the statistics behind the SAT and GRE, to estimate how hard each prompt is and how sharply it separates stronger systems from weaker ones. (This approach was recently called out as a best practice (see p. 11) by leading AI evaluation experts at Princeton.) Results are reported as percentiles against a fixed panel of reference systems, so a score doesn’t depend on who else has been tested.
A model’s score tells you how it behaves as released. Most teams then add a system prompt, retrieval, tools, or an agent loop, and each of those changes how it behaves. Candela can test both, using a local client relay. Scores are designed for comparison across configurations, systems, and time.
A model that declines a harmful request in its originally released form may answer it once a system is fine-tuned, assigned a persona, fed a document with embedded instructions through a RAG, or given text from a trusted tool. The phenomenon works in reverse, too: guardrails put in place around a model that is weaker on safety can make the overall system safer than the original model. Put another way: safety scoring is not composable. Our post on composability goes deeper.
Candela offers three kinds of results.
A MLCommons member company spoke to how Candela’s design and stewardship is an important new piece in the understanding of AI safety across the spectrum of creation and application.
“As AI adoption accelerates, enterprises need credible evidence to make informed decisions about model safety,” said Abby Palia, Principal Product Manager, Responsible AI at Microsoft. “No single benchmark captures the full range of AI safety risks, and as public benchmarks reach saturation, private test sets help keep measurement meaningful. AILuminate keeps its test prompts private, which helps reduce benchmark contamination, and Candela makes these evaluations easier for enterprises to access. At Microsoft, we’re excited to see developers and deployers gain another option for measuring the safety behaviors that matter to them.”
Inside any one organization, AI governance has a well-developed toolkit: in-house evaluations for specific use cases and policies, red teams that hunt for exploitable failures, and monitoring that watches systems in production. Those practices serve the organization that runs them. What’s been missing is a measurement that works across organizations, one that means the same thing to a developer, a buyer, an auditor, and a board. That’s what Candela offers. Every result carries version labels, and MLCommons won’t change what a score means without changing the label, so results can be cited in governance documentation and compared over time.
Regulators and standards bodies face the same challenge at a much bigger scale: rules that apply to everyone work more successfully and fairly when everyone can measure their compliance in the same way. Both are still working out what to require of AI systems, and what’s even possible to measure. As governments and other institutions settle on requirements, our working groups and technical staff are ready to adapt and expand the AILuminate benchmarks to meet them. In the meantime, companies that build a habit of consistently assessing AI safety will be the best prepared for when regulators require it.
Today’s launch is the culmination of the work of over 80 organizations, often alongside competitors. Thank you to every one of them. Thanks also to the MLCommons staff who built the prompt sets, the evaluator, and the service itself.
We think these benchmarks raise the standard for AI safety evaluation; they’ll continue to get better as more organizations use them, share their feedback, and join our working groups. We especially want to hear from enterprise buyers and deployers, because their use cases should shape our new and evolving benchmarks. Here’s how to get going with Candela and MLCommons:
The post Introducing Candela: AI risk benchmarking-as-a-service for developers and deployers appeared first on MLCommons .